From real datasets
Create test sets from unstructured data. Synthesize ground truth from documents or knowledge bases. Continuously enrich your data assets to ensure your evaluations stay accurate, relevant, and up to date.

AI agent evaluation
AgentX provides the AI observability and traceability you need to evaluate AI agents and serve as a reliability guardrail.
Create test sets from unstructured data. Synthesize ground truth from documents or knowledge bases. Continuously enrich your data assets to ensure your evaluations stay accurate, relevant, and up to date.
Measureing consistency with repeated runs. Assess multi-step workflows with multiple interactions. AgentX evaluation embraces the non-deterministic nature while providing reliable metrics.
Don't just run evals. Use them to build a CI/CD pipeline for your agents. Automatically block deployments if evals fail, or promote to production if they pass. Update and deploy your AI agents with confidence.
Runs before deploy and continuously after
Build test set
Run evaluation
Score & surface failures
Threshold decision
Iterate or deploy
Monitor drift
Monitor, analyze, fix
Developers need to know what to fix. So AgentX analyzes agent behavior to pinpoint issues, surface hidden patterns, and prescribe fixes.
Initialization
Main Phase · 517ms
Preprocessing
Main Phase · 75ms
Attachment Processing
Main Phase · 11μs
Onboarding Retrieval
Main Phase · 534ms
Knowledge Retrieval - Initialization
Detailed Phase · 248ms
Knowledge Retrieval - DOC
Detailed Phase · 284ms
Prompt Assembly
Main Phase · 594μs
ReAct Loop
Main Phase · 5.44s
Step 1: LLM Call
Execution Step · 5.09s
Post-processing
Main Phase · 123ms
78.8%vector similarity21.3%jaccard similarity
Hallucinations caused baseless assumptions that led to incorrect decisions.
Suggested fix applied
Restrict the assumption in the system prompt. Add few-shot examples to demonstrate the correct thinking process.
Framework
A strong LLM evaluation framework goes beyond accuracy. These layers cover production AI and LLM testing end to end.
Did the agent complete the task correctly? Essential for any LLM evaluation—beyond single-turn accuracy.
Did tools run as expected? Latency, errors, and correctness of tool outputs. Critical for AI agent evaluation when agents use tools.
Multi-step reasoning quality, coherence, and consistency across runs. Key LLM evaluation metrics for production.
User satisfaction, completion rate, and downstream business KPIs. The top layer of a full agent evaluation framework.
Built for production
AgentX gives you an AI agent evaluation framework built for production: continuous LLM evaluation, regression and benchmark suites, and LLM evaluation metrics tied to business outcomes. Evaluate AI agents at scale.
Product
Everything you need to evaluate, and improve your AI agents, end to end.
Turn production traces into evaluation sets in one click, or drag and drop documents, files, and content to synthesize test cases. Your evals stay grounded in what users actually do.
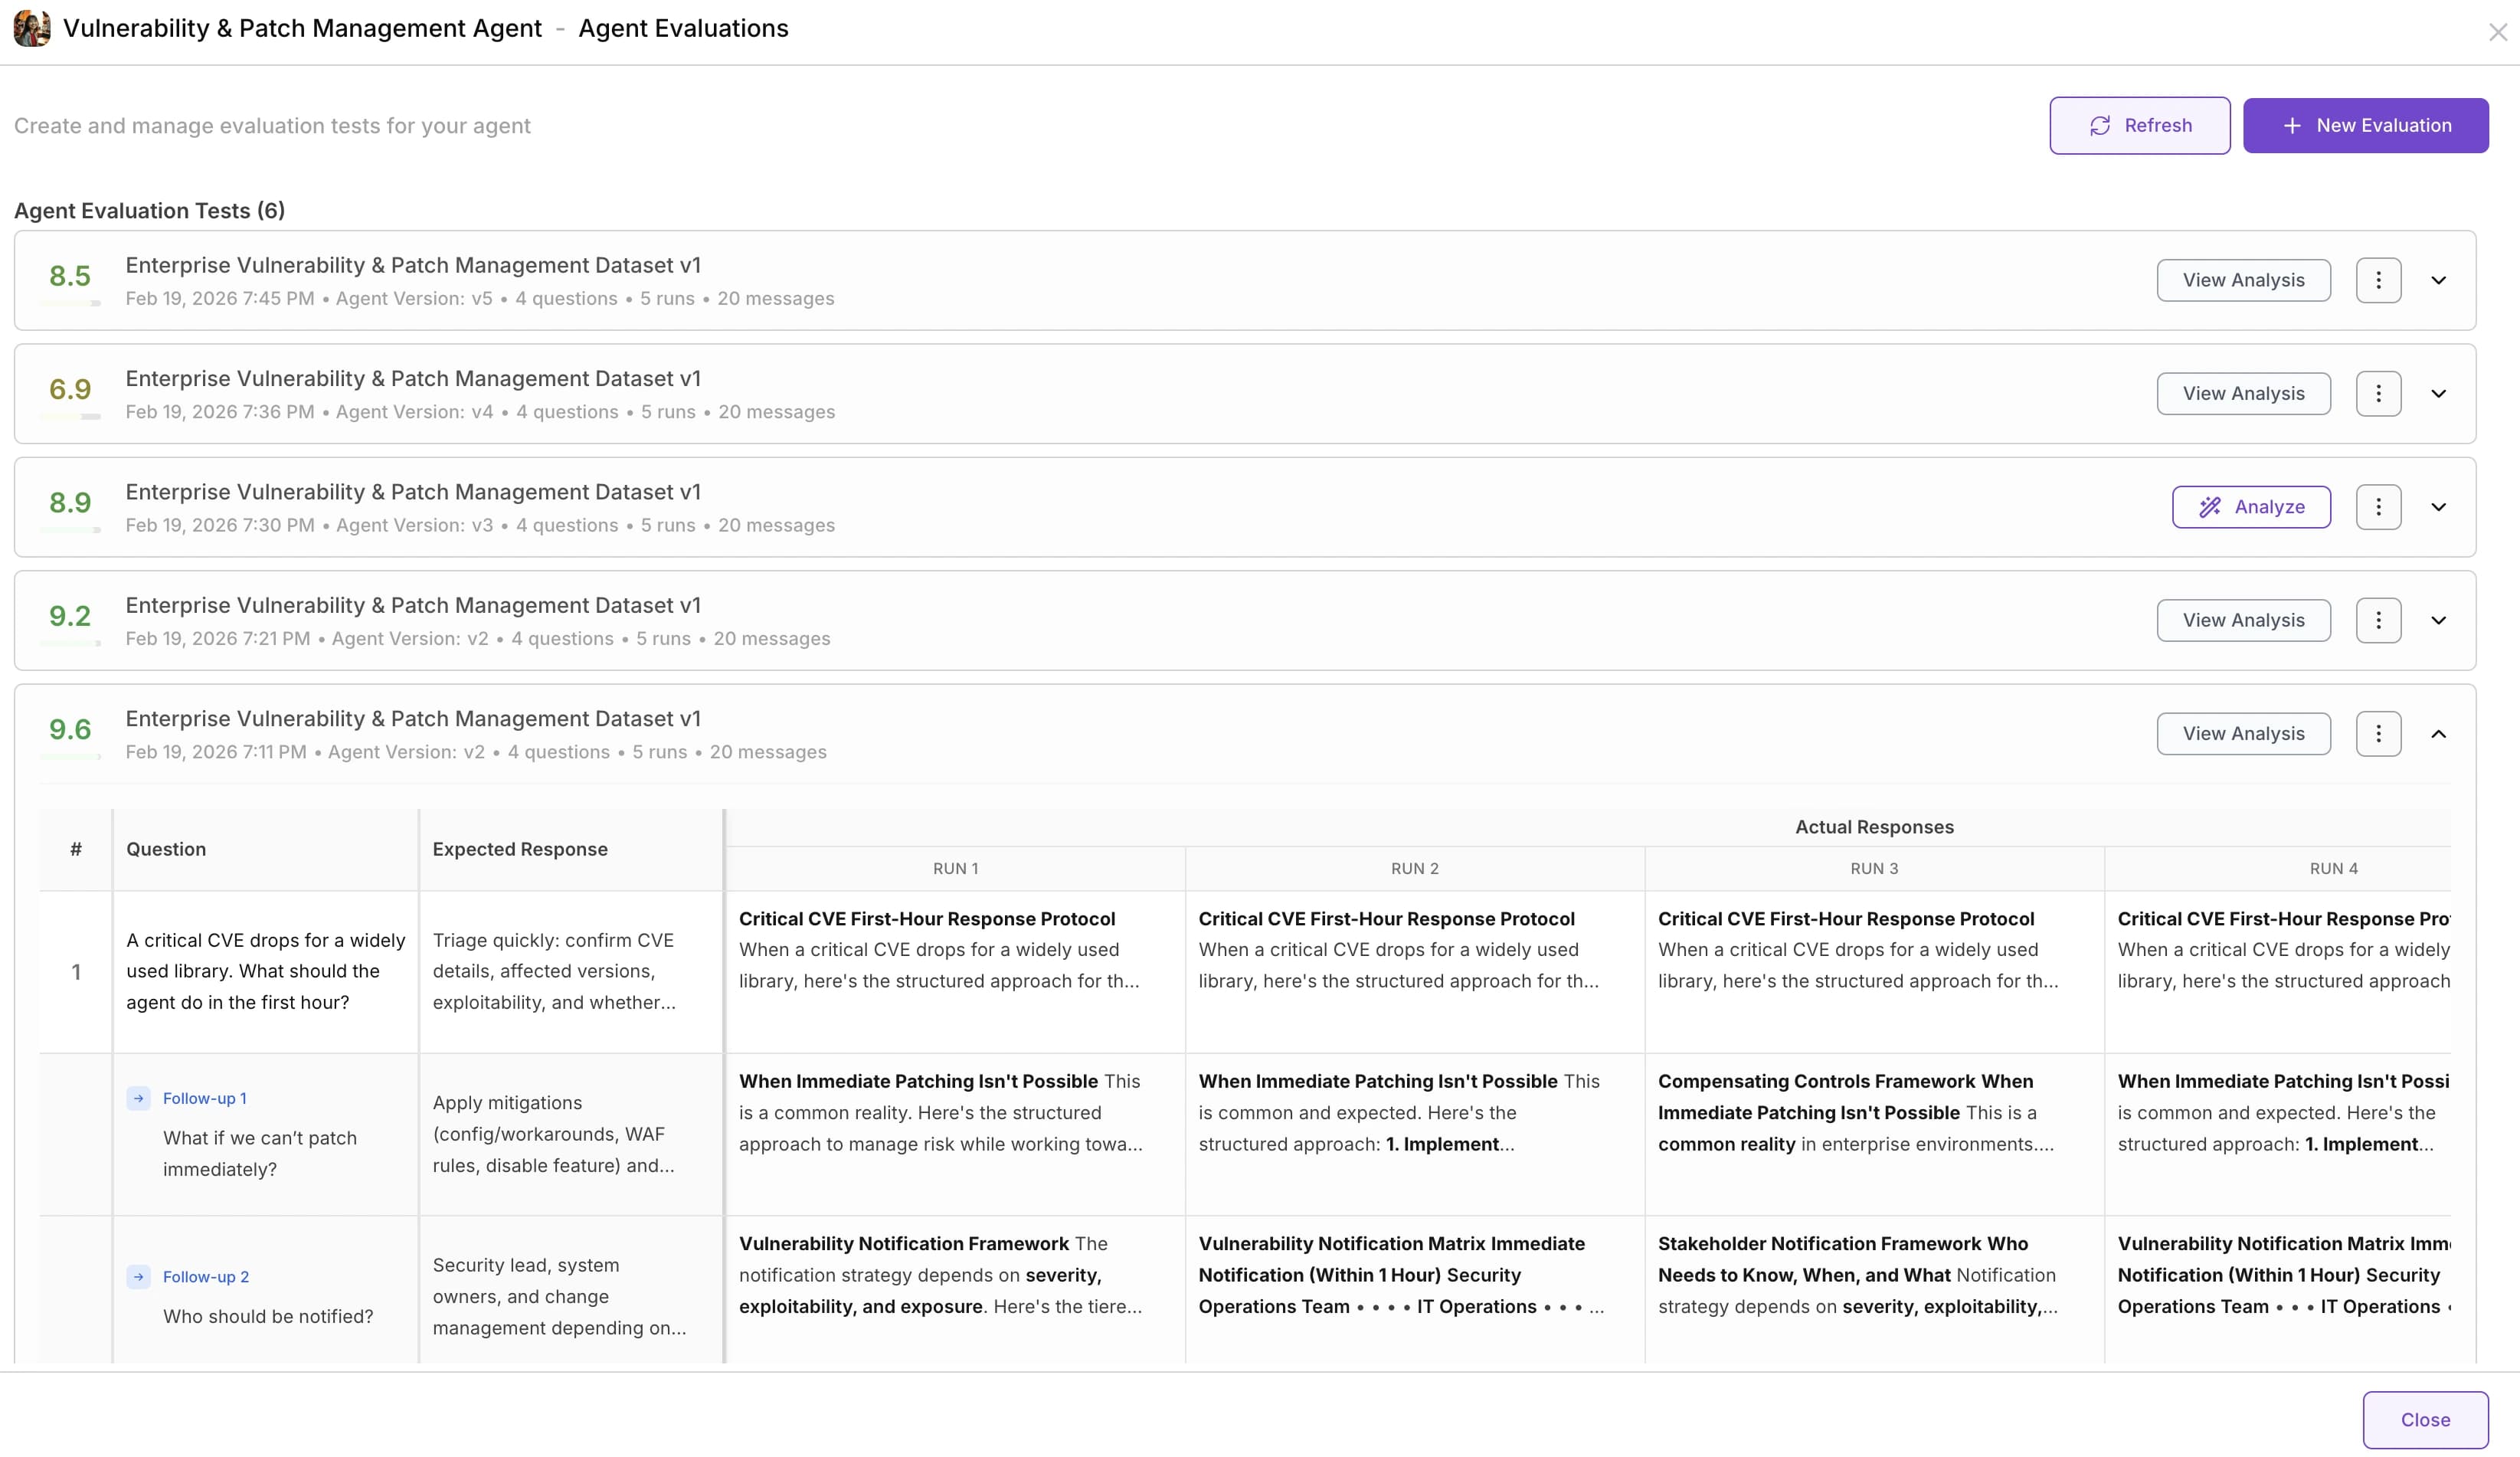
Kick off an evaluation on any agent and instantly see a numerical score across your test set - so you know exactly how it performs before you ship.
Inspect evaluation reports generated from multi-step, multi-agent runs - with every action, tool call, and data layer traced, scored, and explained.
AgentX evaluates with a panel of LLM-as-a-judge models from different vendors, so no single model's bias skews your results. Consensus scoring you can trust.
Apply suggested changes with a single click and re-run the evaluation - iterating until every test passes and your agent is ready to deploy.
Release process
Integrate LLM evaluation into your release process: run before deploy, monitor in production, iterate with a consistent evaluation framework.
Choose layers and KPIs that map to your goals.
Evaluation on every change and in production.
Drift alerts, A/B results, and regression gates.
Wire it into your own stack with the Python SDK: record traces from LangChain, CrewAI, or OpenAI Agents, score runs against test datasets, and gate merges on a pass rate threshold.
FAQ
Common questions about evaluating AI agents to be production-ready.
AI agent evaluation is measuring how well your AI agents or LLMs perform in production - beyond demos. It includes task correctness, tool reliability, reasoning quality, and business impact (completion rate, user satisfaction, drift detection, A/B testing).
Evaluate LLMs in production with a layered framework: (1) task correctness, (2) tool and API reliability, (3) reasoning and consistency, and (4) business and user impact. Use continuous evaluation, regression suites, drift detection, and metrics tied to KPIs like completion rate and user satisfaction.
AI agent evaluation is hard because agents are non-deterministic, use tools and memory, and perform long-horizon, multi-step reasoning. Prompt drift and dataset drift make traditional accuracy metrics insufficient. You need an AI evaluation framework built for production.
We agree. Production data is usually the best source of truth. Our focus is helping teams build evals from real traces and failure cases, while also supporting synthetic generation when coverage gaps exist. The best results come from combining both approaches.
One common surprise is that the most expensive model isn't always the best for a given task. We've seen teams reduce costs significantly while maintaining quality, and we've also seen latency become a bigger issue than model accuracy for some workflows. Sometimes it's really case by case when you need to consider both quality and price. So run it yourself and you will know.
Much less often than people think. In many cases the model is only one piece of the puzzle. Failures often come from missing context, retrieval issues, tool execution problems, or orchestration logic. That's why we focus on full traceability instead of just model outputs.
Exactly. Teams can define evaluation criteria and quality thresholds. If a change causes performance regressions, the evaluation can fail before deployment, similar to how software teams use automated tests to prevent bad releases.
From the blog
From building datasets to running evaluations and turning metrics into business value. Step-by-step guides from the AgentX blog.
Building enterprise-grade evaluation datasets: the foundation of reliable AI agents. Realistic test cases, expected results, capabilities, and follow-ups.
ReadPart 2From dataset to decision: running enterprise AI agent evaluations. Select your agent and dataset, run the evaluation, and get results with justifications and performance metrics.
ReadPart 3How to analyze, interpret, and act on AI agent evaluation results. Root-cause analysis, suggested instruction changes, re-runs to validate - turn evaluation into a release process.
ReadUse the AgentX AI agent evaluation framework to turn your LLMs and agents from demos into measurable, production-grade systems.